
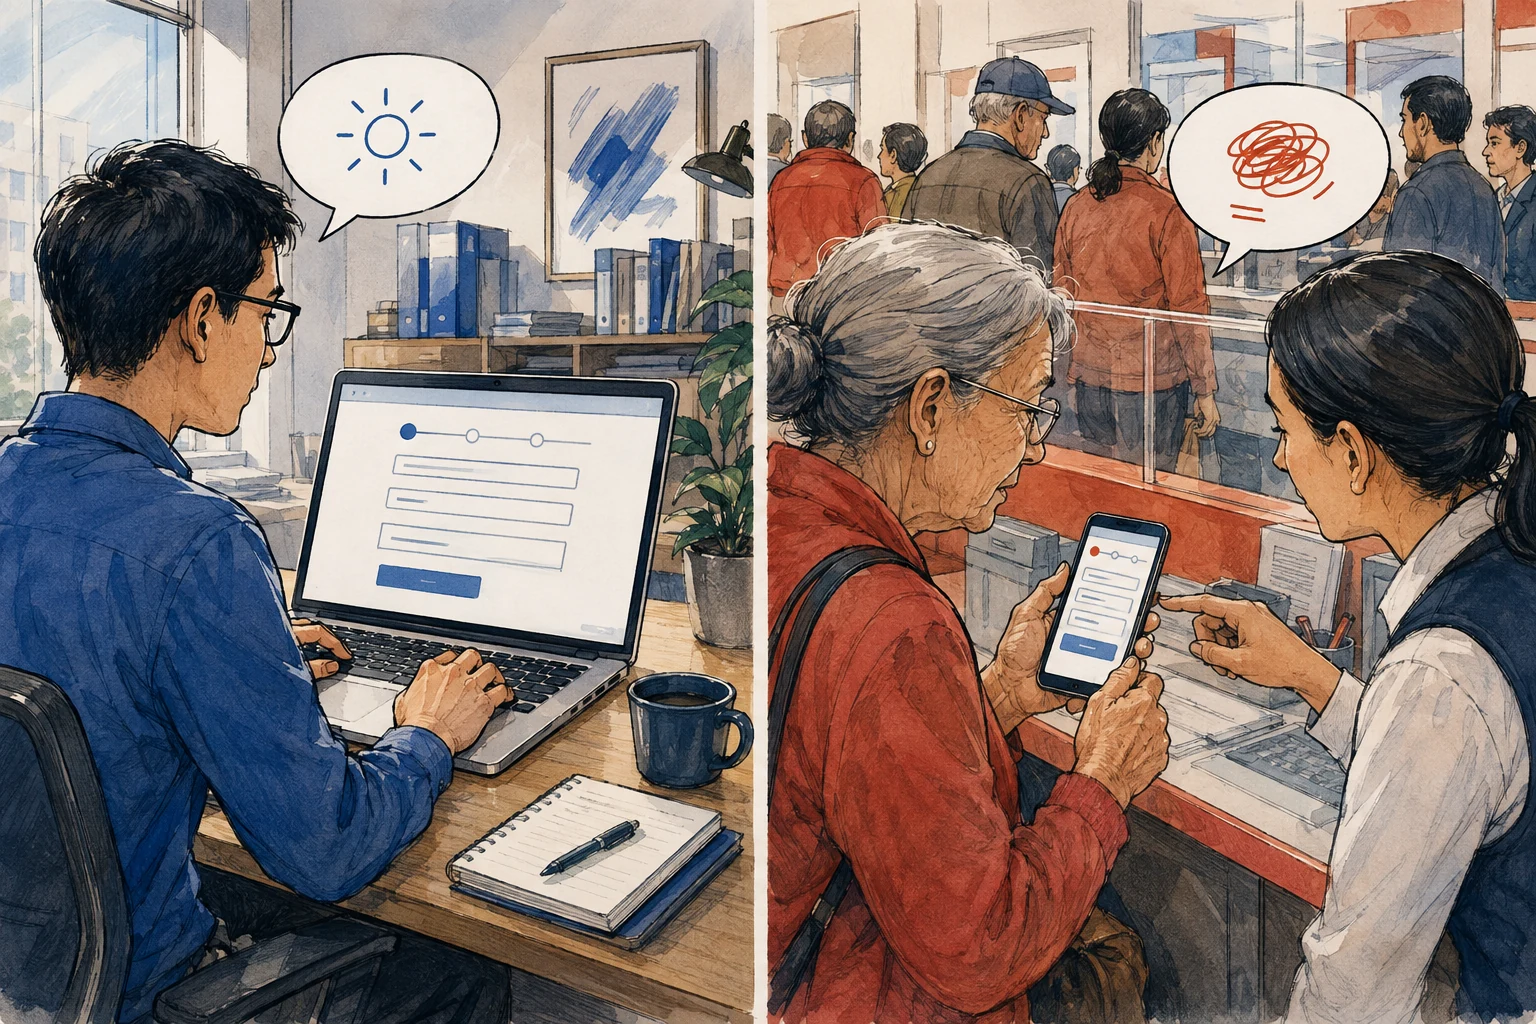
Start with the person trying to use the service.
A person asks an assistant how to apply for a local service. The answer is fluent, but names a document their local office does not issue. Another person gets the right instructions but cannot upload the required file from a shared phone. In both cases, the language may be supported while the task remains unfinished.
A language menu cannot tell you how well a service handles dialect, informal speech, mixed languages, or specialist terms. Nor does it tell you whether the answer fits local rules or the device a person has. When evaluating a local setting, describe these conditions alongside the language itself.
For example, a claim that an assistant answers tax questions accurately needs a country or jurisdiction, tax year, type of taxpayer, language, and task. It also needs a clear way to judge an error. Those details make the claim testable and help readers decide whether the finding applies to their situation.
A fluent answer still needs to work where the person will use it.
Find out what using the service involves.
Before choosing a model or translating a test, describe how people will use it. Will they speak or type? What terms do they use? Which office, professional, or procedure must accept the result? Check devices, connectivity, privacy, cost, accessibility, and any help needed to finish. Ask who would bear the cost of a wrong answer and how it could be corrected.
Choose a method for each question. Bilingual review can check the wording. A local practitioner can check a procedure. Intended users can reveal where the journey breaks down. None of these checks answers everything: a language expert cannot establish whether a phone upload works, and a small user study cannot tell you how common a problem is across the whole population.
Choose settings for what you need to learn, as well as for audience size. Include situations where errors would be costly, language use differs from the development setting, or devices and connectivity impose limits. State who you have not included. When describing a language as “low-resource,” explain which data or research resources are scarce; scarcity is not an inherent limitation of the language.
Check whether the translated task still makes sense.
A translated question may assume an unfamiliar school system, currency, public office, or family relationship. A person can understand every word and still need background knowledge the original audience took for granted. Concepts such as privacy or consent may also need more explanation than a direct translation provides.
Global MMLU examines this problem in a benchmark extended to forty-two languages. The paper classifies 28% of annotated questions as requiring cultural, geographic, or dialect knowledge, with geographic references largely focused on North America or Europe. Model rankings changed when culturally sensitive questions were evaluated separately.[1] Translating an English test therefore does not by itself show how well a model handles local knowledge.
Check the wording, the meaning of the concept, and the action a correct answer would support. Ask bilingual reviewers to compare versions, and ask intended users to explain how they understood a question. Include examples that would expose an imported assumption. Translating a passage back into its original language can reveal wording changes, but cannot establish that the original task is appropriate locally.
Measure the effort needed to finish.
Models process text in units called tokens, and the same information can take different numbers of tokens in different languages. That can affect cost and how much text fits in a request. A 2023 study covering twenty-two diverse languages found that speakers of many supported languages faced higher token-based charges while receiving poorer results.[2] These findings concern the services tested, but show why an accuracy score alone is not enough.
Try the complete task in each language. Record response time, failures, retries, cost, and how many exchanges it takes to get a usable result. Check speech recognition, typing, fonts, document reading, names, addresses, and date formats. A good answer to a carefully typed question is of little use if an earlier step misreads the person’s actual input.
Look separately at long documents and extended conversations. If one language needs more tokens, the system may cut off evidence sooner. Also record the effort people spend correcting answers, finding help, or switching to another service. Compare the cost of a completed task, including repairs, rather than the advertised price of one request.
Compare the effort and cost of finishing the task, including corrections.
Build tests from situations people encounter locally.
Work with intended users and practitioners to collect relevant forms, questions, terminology, and reported failures, with appropriate consent. Ask what a useful answer would let someone do and what the system must not assume. Begin with these situations before deciding which imported test questions are worth translating.
You can organize the tests into three groups. Use a shared group for tasks that make sense across settings, a locally written group for specific knowledge and procedures, and a comparison group that changes one condition while keeping the goal the same. Label questions that depend on cultural knowledge so a combined score does not hide that dependence.
Agree with local reviewers on what counts as a good answer before they score results. Include acceptable variations, necessary evidence, unsafe advice, and when the system should ask for help. Judge whether the answer supports the task, not just whether it matches one preferred style. When reviewers disagree, investigate whether they represent different regions, roles, or experiences.
Use the comparison to identify what needs testing with local users and practitioners. Translation review covers only part of the work.
Test the ways people actually speak and write.
Include informal wording, dialect, honorifics, mixed scripts, spelling errors, incomplete sentences, and corrections after a misunderstanding. In a 2024 study of ten English dialects, native-speaker reviewers found more stereotyping, demeaning content, misunderstanding, and condescension in responses to non-standard varieties from the models tested.[3] One overall English score would have hidden those differences.
Safety also needs its own local checks. A study using matched malicious prompts found that the tested systems gave unsafe and irrelevant answers more often in lower-resource languages.[4] A safeguard tested in one language cannot simply be assumed to work in another. Test appropriate refusals, uncertainty, and access to human help in the forms of language relevant to the service.
Create paired cases to examine a specific change: formal versus conversational wording, a local versus an imported name, or one language versus a mixture. Compare what the system understood, asked, answered, refused, and referred onward. If the behavior changes, investigate whether the problem began with input recognition, missing knowledge, a safety rule, scoring, or another part of the application.
Let local contributors shape the research.
Asking a model to act as a resident does not establish that its response represents local views. Experiments comparing Chinese and English found systematic changes in generated responses on measures of social orientation and thinking style.[5] This shows that language can change a model’s behavior. It does not make either response a reliable account of the people who use that language.
People within a group also disagree. A study comparing model responses with US public-opinion data found substantial differences from the views of demographic groups, including after prompts asked for a particular group’s perspective.[6] Generated answers can help rehearse a question or reveal an assumption to test. They cannot supply missing participant evidence.
Involve local contributors in choosing questions, creating data, defining evaluation, interpreting results, and deciding readiness for use. Participatory work on African-language translation produced new datasets and benchmarks for more than thirty languages, with human evaluation for about a third of them. Participants without formal machine-learning training contributed to the research.[8] Give contributors a say before the task is fixed, rather than asking them only to review a finished translation.
Local contributors should help choose the questions, not just review the translation.
Say where the service has been tested.
Report the languages and varieties tested, the local tasks, and the conditions of use. Explain which questions were translated, which were written locally, and who participated and reviewed the answers. Show relevant differences in completion, errors, cost, and correction effort. Name the important settings that remain untested.
The NLLB translation project combined data creation, language identification, modeling, and human evaluation to cover two hundred languages.[7] That is a substantial achievement. Whether a service works in a particular office, domain, or mode of communication still needs investigation. A language list shows where to begin asking those questions.
Limit rollout to the uses that meet the agreed local criteria, with a clear route to human help for uncertain or consequential cases. Monitor completion, retries, corrections, and dropouts alongside complaints. Few complaints may mean people could not find or finish the service. Review the evidence when the model, rules, interface, or local practices change.